There are many ways to use LLMs. In this article, I want to focus on tasks that generate natural language shown directly to users.
For example, a stock-trading app might explain why a stock price moved recently. A dating app might generate a recommendation such as “Why not meet this person?” based on what two people have in common or why they were matched.
At first glance, prompt engineering for these features looks simple.
- Define the product policy and write a prompt.
- Review the prompt's output.
- Revise the policy and prompt based on the result.
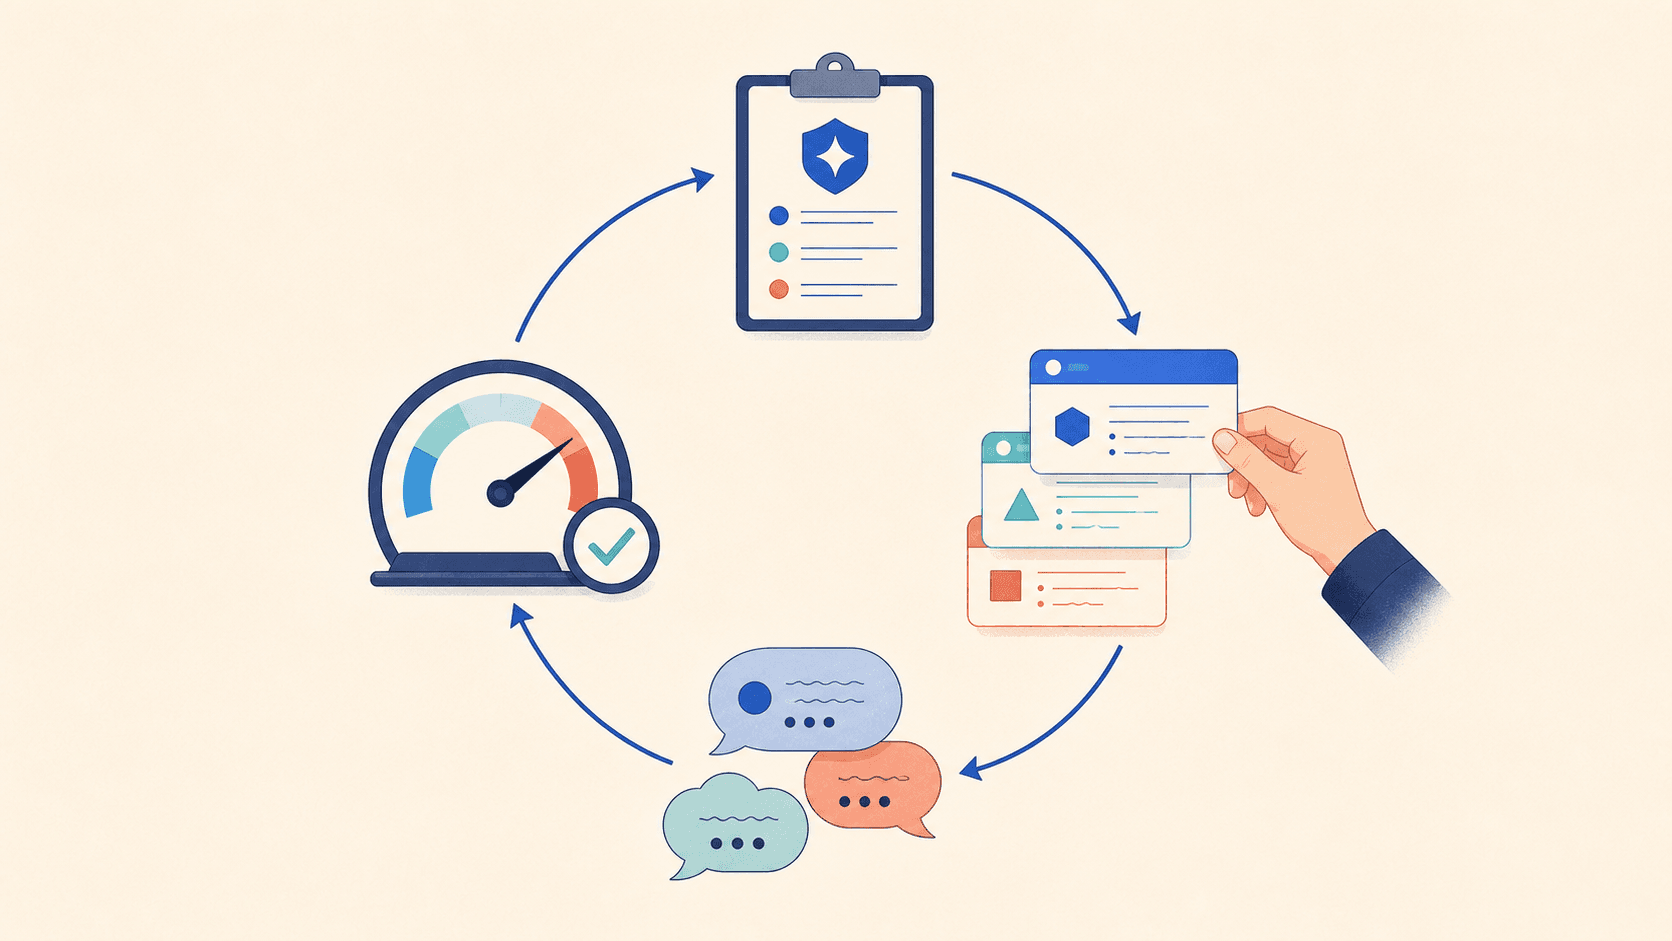
Policy, prompt, output, and evaluation are not one-off stages. Together, they form a recurring improvement cycle.
For a simple problem, this cycle can be repeated quickly. But as the problem grows more complex and more policies need to be reflected in the output, iteration slows dramatically. The hard part is no longer changing a line in the prompt. It is agreeing on what good output means and verifying that the change actually made things better.
Assuming that the model itself remains unchanged, this article examines why improving prompts for natural-language output is so difficult.
Two situations that call for prompt improvement
There are two broad situations in which a prompt needs to be improved.
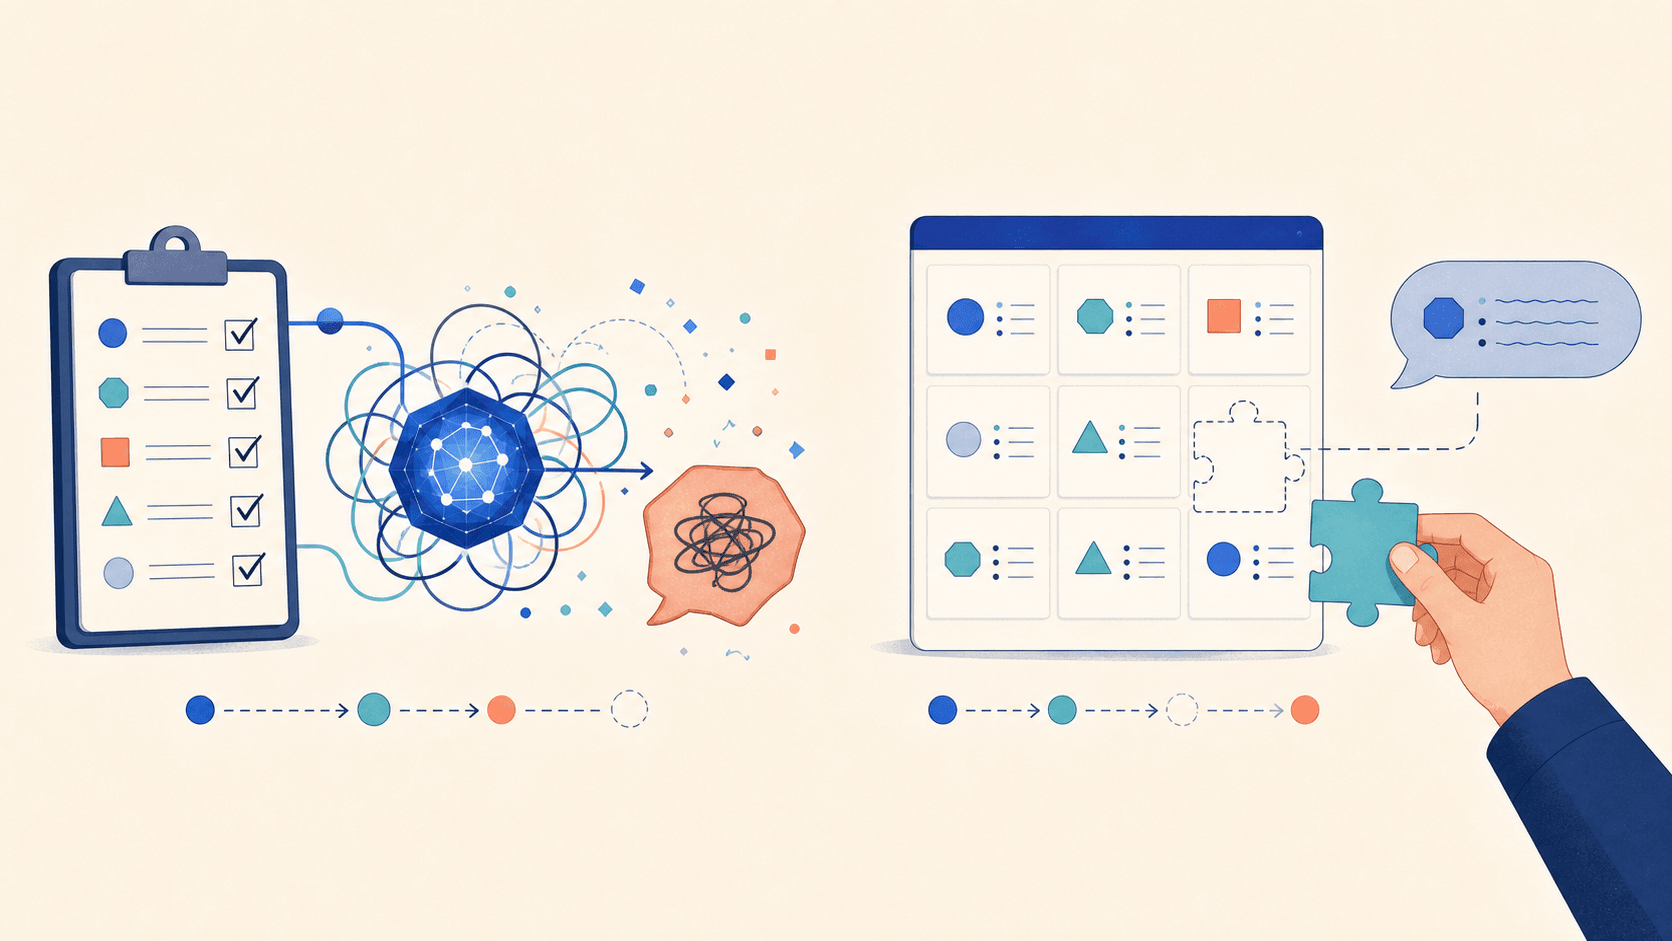
A model failing to execute an existing policy and an output exposing a gap in that policy are two different problems.
1. A policy exists, but the output does not follow it
This happens when the result does not behave as intended even though the prompt includes an explicit rule. The rule may be ambiguous, it may conflict with another rule, or its priority may not be clear enough. In this case, the structure and wording of the prompt need to be improved so the model can understand and follow the policy's intent more reliably.
2. The output reveals the need for a new policy
An unexpected output may lead to a new requirement: “In a case like this, the product should behave this way.” This is not merely a prompt-writing problem. A new product or operational policy must be defined first.
Distinguishing the two situations matters. The first is about executing an established policy more faithfully; the second is about closing a gap in the policy itself. Because the causes differ, the solutions should differ as well.
Why prompt optimization is slow and difficult
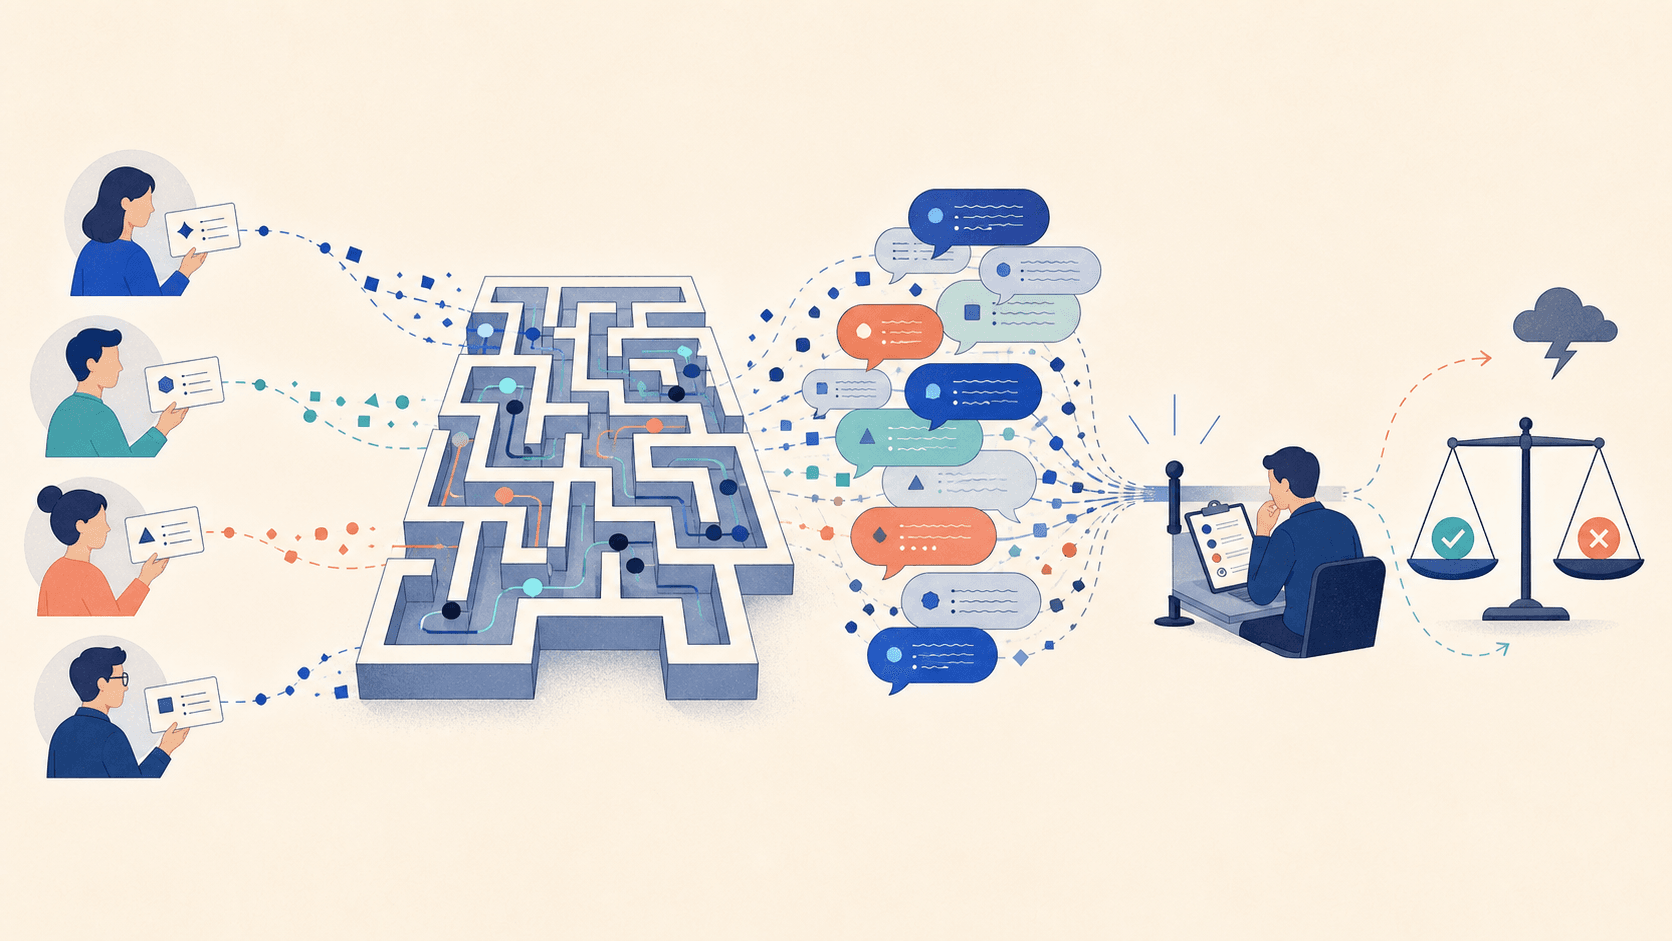
Scattered policies and varied outputs pass through a complex evaluation process, eventually creating a bottleneck at the point of human review.
Policies are scattered across many places
When several stakeholders review an output, they produce many kinds of feedback. The problem begins when that feedback is spread across chat messages, meeting notes, issue trackers, and other tools.
One person might say, “The sentence is too stiff,” while another says, “The tone is too casual.” Unless these opinions are gathered in one place, it is difficult to identify conflicting requirements or turn one-off feedback into a consistent policy. Only fragments of feedback end up being patched into the prompt, and over time even the reason a rule was added becomes difficult to recover.
Policies should therefore be managed in a single source of truth (SSOT). That source should record not only the final rules, but also why each rule exists, its exceptions, and its priority.
It is difficult to tell whether a revised prompt is actually better
Fixing one failure case does not guarantee that the revised prompt produces better results for other inputs. Solving one wording problem may make a case that previously worked well perform worse. In other words, prompt changes can introduce regressions just like ordinary software changes.
Without clear policies and evaluation criteria, regression testing is impossible. Looking at a handful of outputs and deciding that they “feel better” is not enough to conclude that overall performance has improved.
Natural-language output rarely has one correct answer
For classification or extraction tasks, a correct answer can often be defined clearly. Natural-language generation is different: several very different sentences may all be good answers. If the ground truth (GT) is defined as a single ideal sentence, a valid result may be marked as a failure simply because it uses different wording.
For natural-language generation, GT is closer to a set of conditions that a good output must satisfy than to one correct sentence. Those conditions might include:
- Information that must be included
- Expressions or content that must not be included
- Required tone and sentence length
- Factual consistency with the input data
- Priority when policies conflict
A test case should therefore store more than an input and an expected output. It should also record the evaluation criteria the case must pass and the reasons it may fail.
Humans cannot review every result
Human evaluation is important, but it does not scale to reviewing every combination of prompt version and test case. As the test suite grows, review takes longer and differences between evaluators become more likely.
Items that can be judged mechanically, such as forbidden words or formatting constraints, should be handled by rule-based checks. Qualitative criteria such as meaning and tone can be evaluated with models. Human reviewers can then focus on boundary cases and results for which automated evaluation is uncertain.
Intuition-only changes are difficult to reproduce
There is nothing inherently wrong with a person editing a prompt. The problem is changing the wording by intuition without recording why the change was made or how it performed. This makes mistakes more likely, makes it difficult to explain which change improved performance, and makes returning safely to a previous version harder.
Prompts, policies, evaluation datasets, and evaluation results should be versioned and linked together. Only then can teams compare before-and-after results, reproduce improvements, and roll back when necessary.
What faster and more reliable improvement requires
Improving the speed and quality of prompt iteration ultimately requires the following foundations.
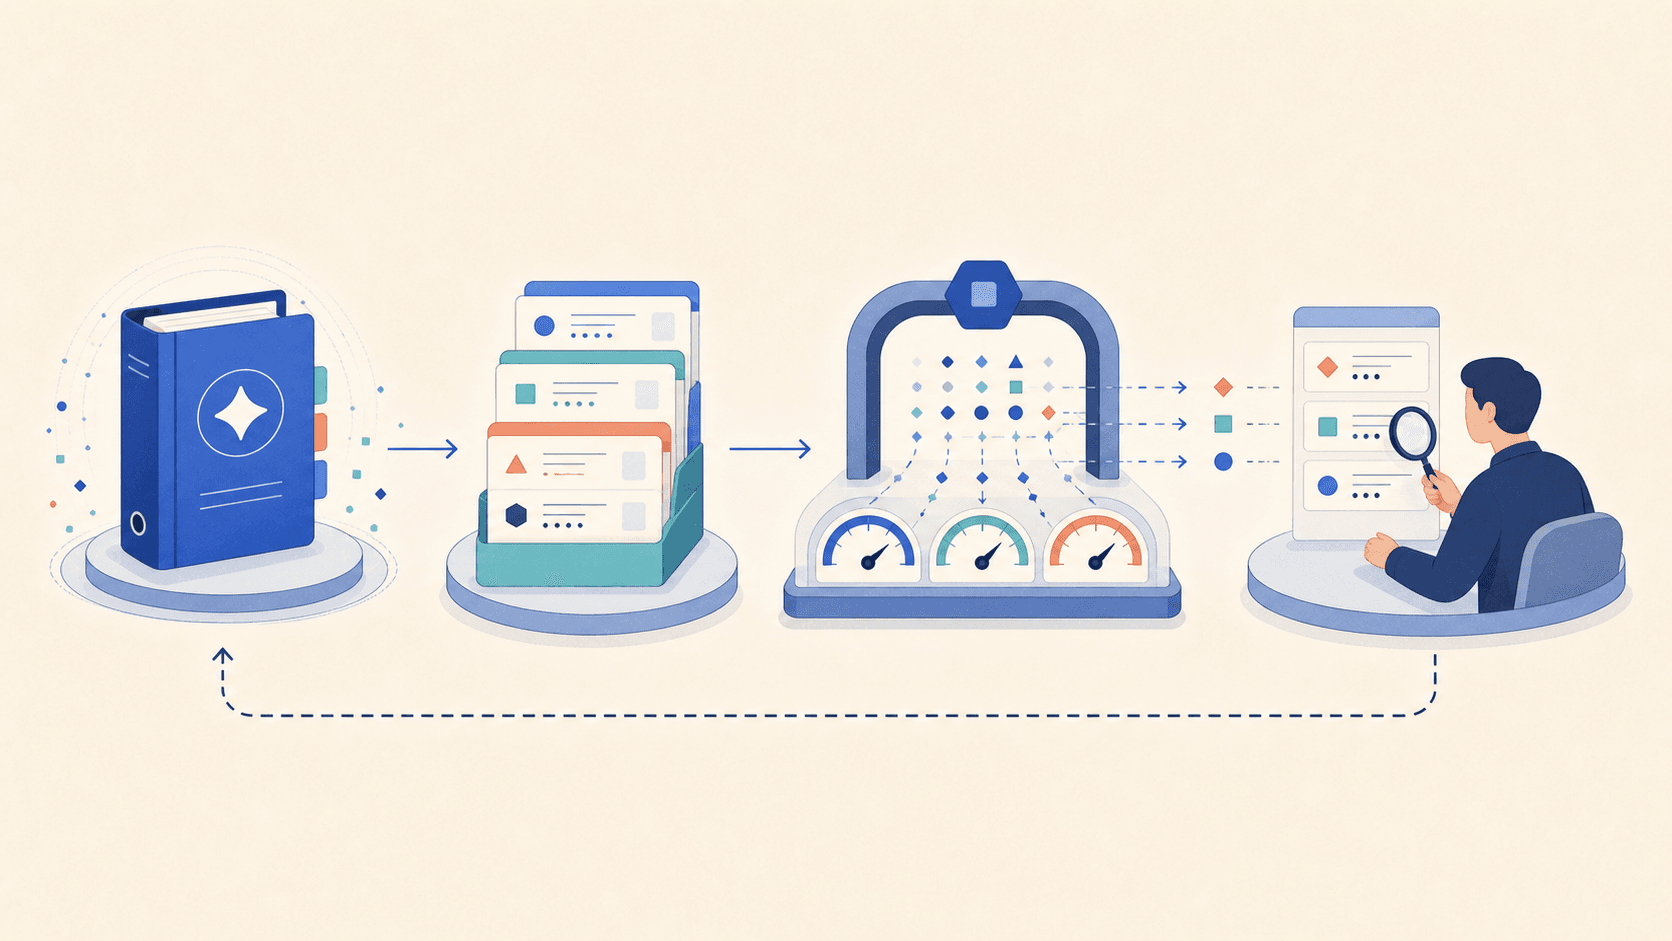
Policies, evaluation datasets, automated regression evaluation, and human review of boundary cases should form a single feedback loop.
- Centralized policy management: Manage policies, exceptions, priorities, and the reasons for changes in one SSOT.
- Versioned evaluation datasets: Accumulate real failures as test cases and record each case's evaluation criteria and failure reasons.
- Automated regression evaluation: Run the full test suite whenever the prompt changes and compare results before and after the change.
- Efficient human review: Review cases that are difficult to evaluate automatically or for which the evaluation is uncertain, rather than reviewing every output.
- Traceable experiments: Preserve the connections among the policy, prompt, model, evaluation set, and result used in each experiment.
When GT is clear, there are already many ways to automate prompt optimization. But when the evaluation criteria are vague, automated optimization only optimizes the wrong objective faster. Before automating, teams must define clearly what counts as good output.
Closing thoughts
For complex natural-language generation tasks, the real target of optimization is not a single piece of prompt wording. It is the entire process of defining policies, accumulating real cases as evaluation data, and repeatedly verifying the effects of change.
People should focus on deciding policy and judging ambiguous boundary cases. Systems should repeatedly check criteria that have already been agreed upon and track the history of changes. When those roles are separated, prompt improvement can evolve from a craft dependent on individual intuition into a reproducible engineering process.
Share your thoughts on this article.
Sign in with GitHub to leave a comment or reaction.